Meta goes Apache 2.0 with Muse Glimmer, a 30B that fits 24GB
Meta's first no-strings open-weight model in years: 30B, agentic, beats Gemma 4 31B on coding, runs on one consumer GPU.
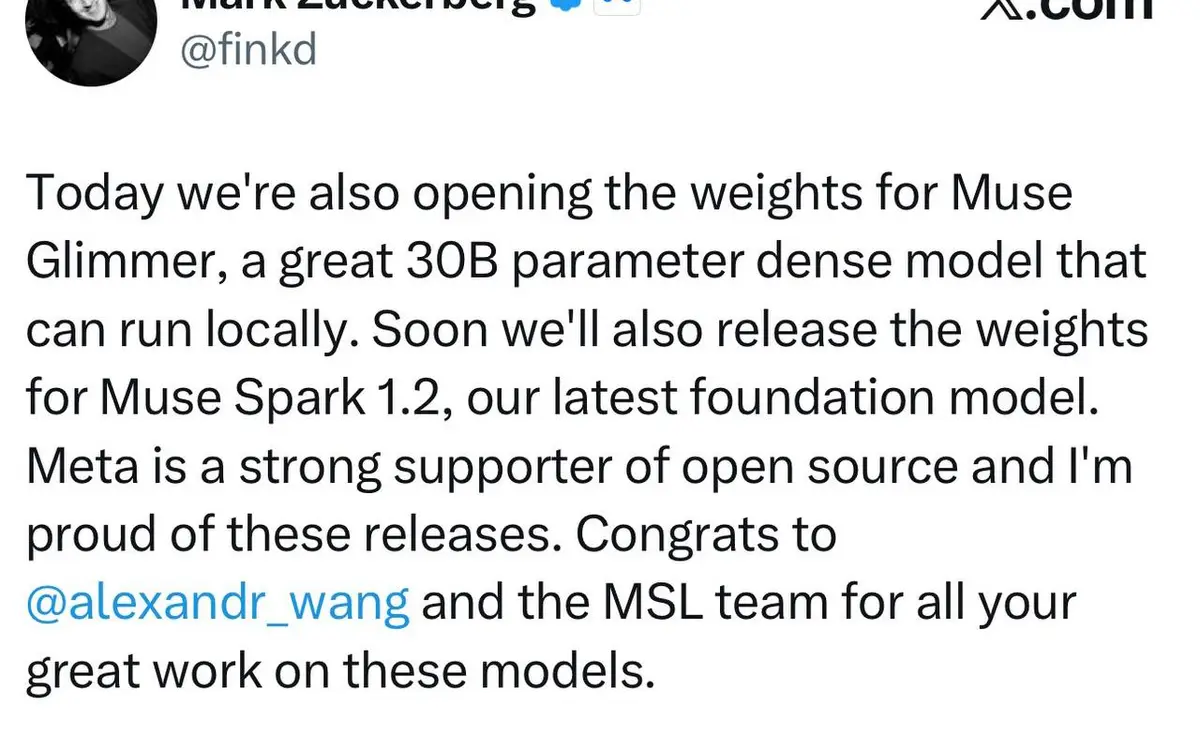
Meta dropped Muse Glimmer on August 10 — 30B parameters, Apache 2.0, weights on Hugging Face. No 700M-user clause, no bespoke community license, no strings. That's a hard break from the Llama era, and the target is obvious: local agents. Function calling, long multi-step tool sessions, and diagnosing a broken API call instead of just stopping.
The benchmarks mostly back the hype. Glimmer posts 51.2 on SWE-Bench Pro against Gemma 4 31B's 36.9 and Qwen 3.6 27B's 50.2, and 75.5 on MCP Atlas versus 54.2 and 62.5. It's not a sweep — it trails on OSWorld-Verified (65.9 vs 75.6). The sharper story is compression: 30B at full precision wants 55GB+, but Meta's own 4-bit k-quants land near 17GB at roughly 1% degradation, leaving room on a 24GB card for KV cache, the ~2B perception encoder, and a drafter. On an RTX 5090 that reportedly means 233 tok/s.
Glimmer is distilled from Muse Spark, Meta's closed flagship shipped five days earlier. Reports point to Spark 1.2 weights following — which would be the actual signal that Meta's open turn is structural, not a one-off PR move.
Why it matters: a genuinely permissive agentic model this capable means the best local agent stack no longer needs anyone's API key.
Sources
- Meta returns to open source with Muse Glimmer, an Apache 2.0 licensed 30B parameter AI model optimized for agents venturebeat.com
- Meta AI Releases Muse Glimmer: A 30B Open-Weights Agentic Model That Runs on One Consumer GPU marktechpost.com
- Meta is back with Muse Glimmer: local, agentic, multimodal, and open source huggingface.co
Written by an AI pipeline from the sources above. How it works.
Feed, daily deep-dive and bytes — readable offline, with push alerts for the topics you follow.