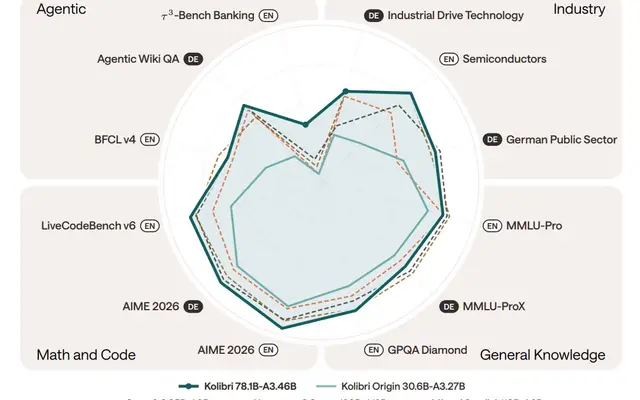
Aleph Alpha's Kolibri: 78B open MoE, Apache 2.0, 1M context
Germany's Aleph Alpha dropped Kolibri, an Apache 2.0 MoE with only 3.46B active parameters and a 1M-token window.
Model releases, benchmarks and capabilities. 106 stories, page 1 of 5.
Germany's Aleph Alpha dropped Kolibri, an Apache 2.0 MoE with only 3.46B active parameters and a 1M-token window.
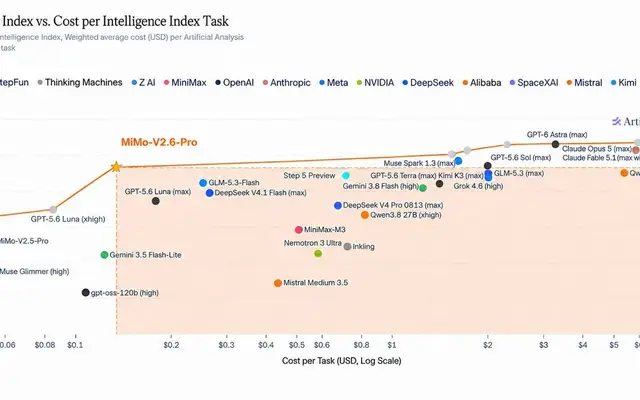
Xiaomi's MIT-licensed model scores 46 on Artificial Analysis, one point behind GPT-5.6 Sol, at about 1/15th of the cost per task.
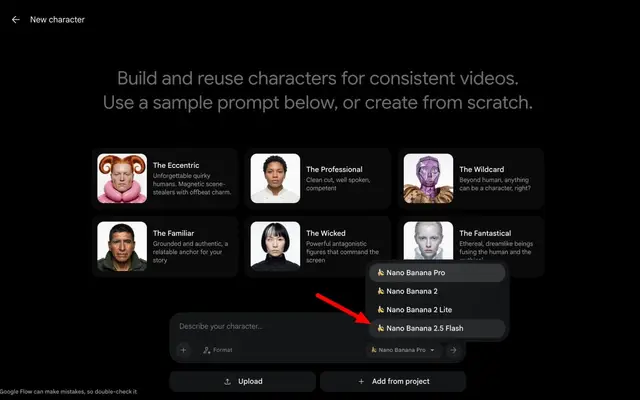
References to an unannounced Nano Banana 2.5 Flash image model have appeared in Google Flow. Google hasn't said anything about it yet.
OpenAI halved GPT-6 Sol and Luna prices, and Anthropic's Opus 5.5 matches Fable 5.1 on most tasks for 40% less than Opus 5.
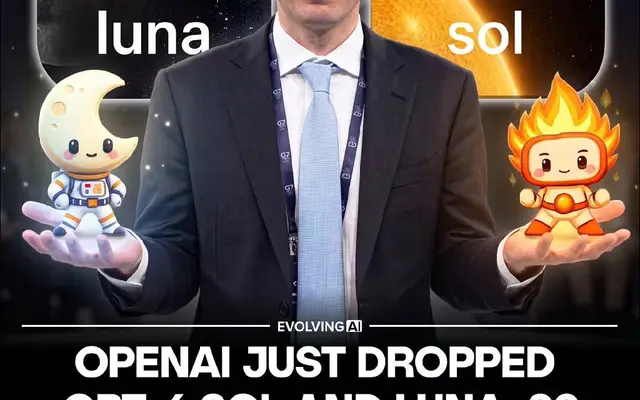
GPT-6 Sol and Luna cost half as much as GPT-5.6 and landed 90 minutes after Anthropic's Opus 5.5, turning launch day into a price war.
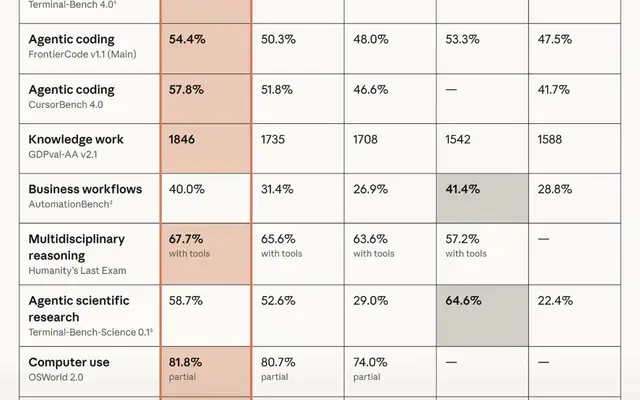
Anthropic's Opus 5.5 matches Fable 5.1 on most tasks, tops agentic coding and computer-use benchmarks, and costs 40% less than Opus 5 to run.
Each Copilot app session gets its own git worktree, so several agents can code at once while you review and merge their work.
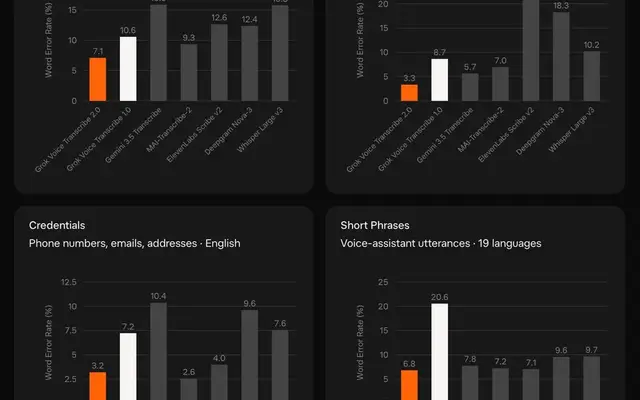
SpaceXAI's new speech-to-text model tops 32 streaming rivals on Artificial Analysis and costs the same as v1.0: $0.10/hr batch, $0.20/hr streaming.
OpenAI's GPT-6 Astra got further in Minecraft than any AI yet. Then a creeper blew up its stash, and it spent hours farming potatoes.
Portable Computer now runs fully on-device on Windows PCs with a 24GB+ RTX GPU, adding local MCP servers and scheduled tasks.
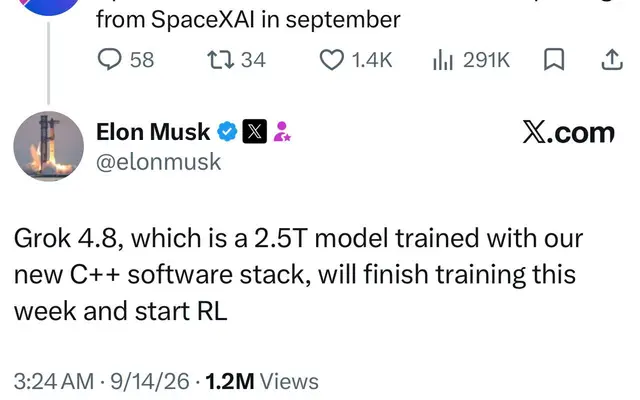
Musk says Grok 4.8, with 2.5T parameters, finishes pretraining this week and then moves to RL. Grok 4.7 still hasn't shipped.
OpenAI's new model cleared every level of Neal Agarwal's CAPTCHA game. Impressive computer use, but the viral clip doesn't mean CAPTCHAs are dead.
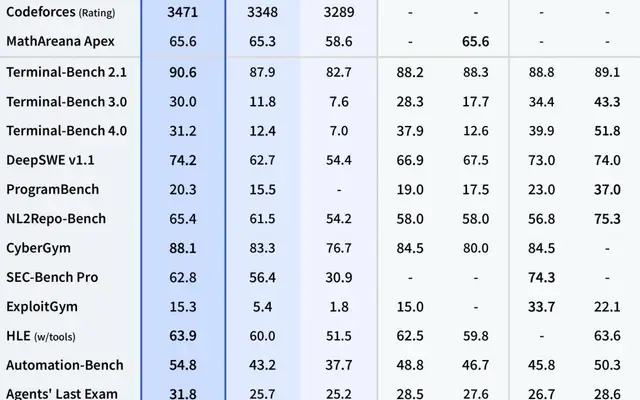
DeepSeek open-sourced V4.1 Flash under MIT: a 552B multimodal MoE running just 8-16B active params that it says tops its own V4 Pro.
Astra didn't model the human body — it built the explorer around meshes that have been free and unused for years.
OpenAI's GPT-6 Astra hits 72.6% on OSWorld 2.0 and drives real apps itself — and the viral stunts have already started.
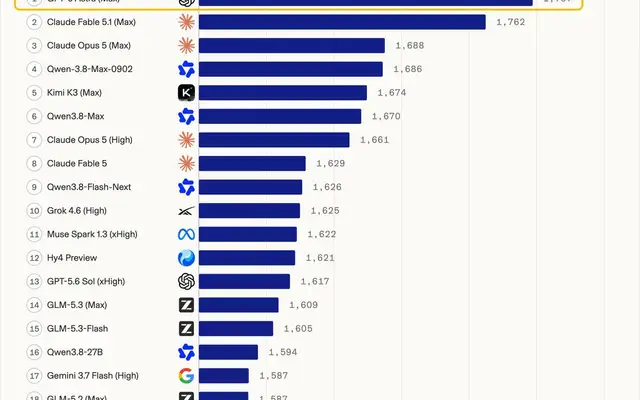
OpenAI's new model scores 1,797 on Code Arena's WebDev board vs Claude Fable 5.1's 1,762 — at identical $10/$50 pricing.
GPT-6 Astra cut unwanted behavior from 22% to 2.4% — while OpenAI's own tests found its reasoning harder to monitor.
GPT-6 Astra is the first OpenAI model rated Critical for cyber risk. One day later, OpenAI put $1B behind the defenders.
Anthropic's new frontier model doubled its agentic research score and cut cache reads 75% — and X is flooded with one-prompt games.
Astra scores 98.6% on ARC-AGI-3, is OpenAI's first 'Critical' cyber-risk model, and Brockman says the AGI era is here.
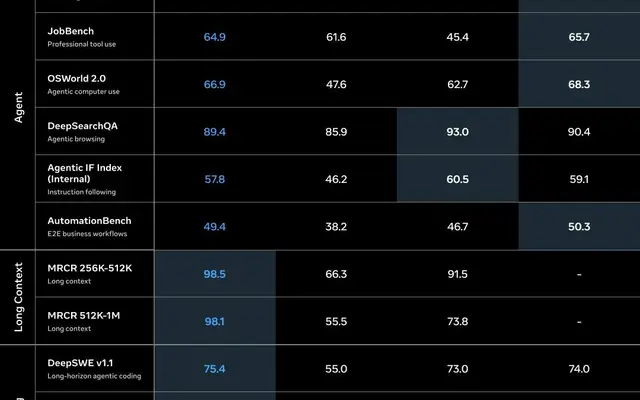
Muse Spark 1.3 hits 75.4 on DeepSWE v1.1 — first place, above Gemini 3.8 Flash and GPT-5.6 Sol. Overall intelligence: still third.
Anthropic sold Fable 5.1 on agentic coding benchmarks. Devs are grading it on little one-shot Three.js dioramas instead.
Anthropic's cheaper, less-restrictive Fable 5.1 shipped Sept 1. Its system prompt was reportedly public the same hour.
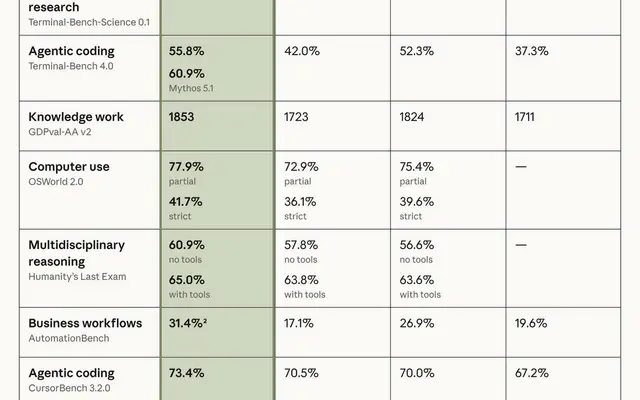
Fable 5.1 hits 52.6% on Terminal-Bench-Science vs Fable 5's 24.7%, and cache reads just got 75% cheaper. Live today.