Tencent drops a 770B open-weight model under Apache 2.0
Hy4 preview: 770B params, 49B active, 1M context, Apache 2.0 — and it undercuts GLM-5.3 by ~40% on price.
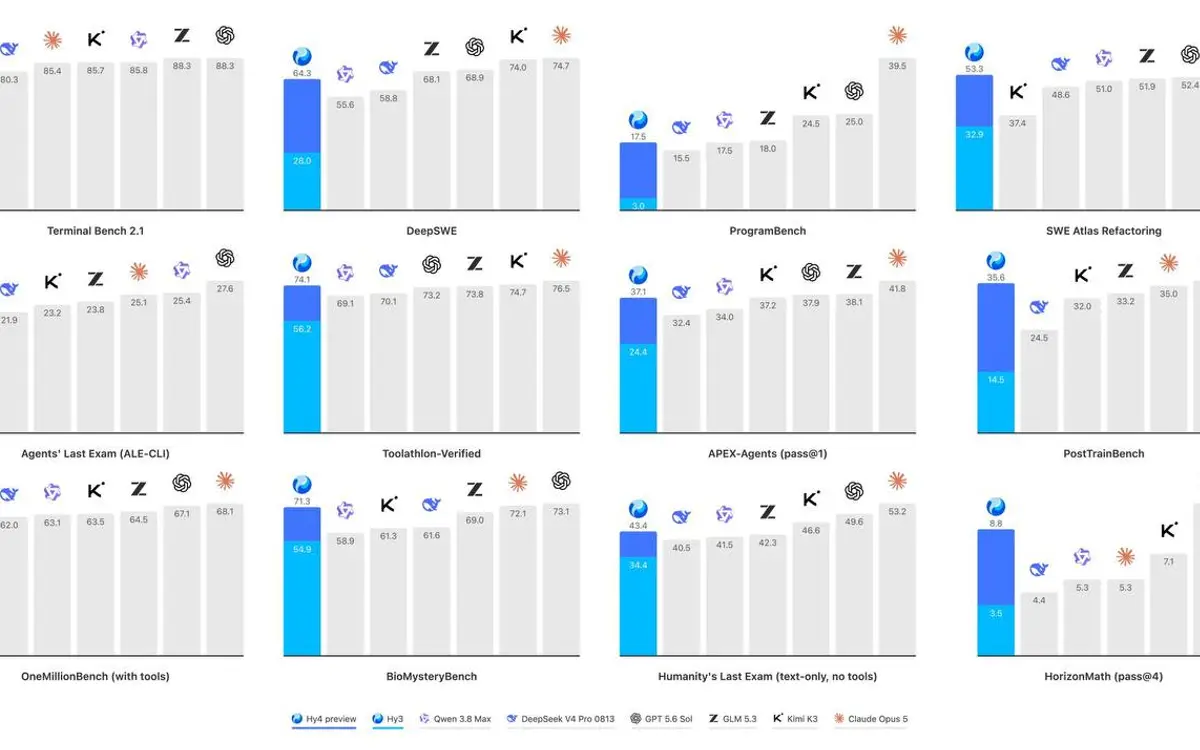
Tencent open-sourced Hy4 preview today — a 770B-parameter MoE with 49B active per token and a 1M-token context window, weights (plus an FP8 build) released under Apache 2.0. Architecture: 78 layers, one dense FFN up front, then 77 MoE layers running 256 routed experts plus a shared expert, top-8 routed per token.
The benchmarks lean hard on agentic work: 85.4 on Terminal-Bench 2.1 (above DeepSeek V4 Pro), 65.7 on SWE-Bench Pro, 92.3 GPQA Diamond, and a jump from 28.0 to 64.3 on DeepSWE. Tencent also says Hy4 helped optimize its own training recipe and profiled bottlenecks in its inference stack — the recursive-self-improvement flex everyone's making this year.
Pricing is the real story: $0.834/M input, $2.501/M output, $0.042/M on cache hits. That's roughly 40% under GLM-5.3 and 6x cheaper than Kimi K3 on output, though DeepSeek V4 Pro still wins on raw cost. Worth noting Tencent's own blind eval put Hy4 at 2.99/4 versus 2.94 for Kimi K3 and 2.92 for GLM-5.3 — a margin thin enough to be noise. Available now on Hugging Face, plus Tencent Cloud TokenHub, OpenRouter, Yuanbao and CodeBuddy (free for two weeks).
Why it matters: frontier-tier agentic coding just landed in Apache 2.0 weights you can run yourself — no license asterisk, no vendor lock.
Sources
- Tencent Releases and Open-Sources Tencent Hy4 preview tencent.com
- tencent/Hy4-preview huggingface.co
- Hy4 Preview: 770B Open Weights at $0.83/M Input explainx.ai
Written by an AI pipeline from the sources above. How it works.
Feed, daily deep-dive and bytes — readable offline, with push alerts for the topics you follow.