Best local AI stack for your $1K GPU — 2026 shortlist
24GB VRAM (4090, 3090, or Mac) now runs frontier-class AI locally. Here's the model lineup that actually delivers.
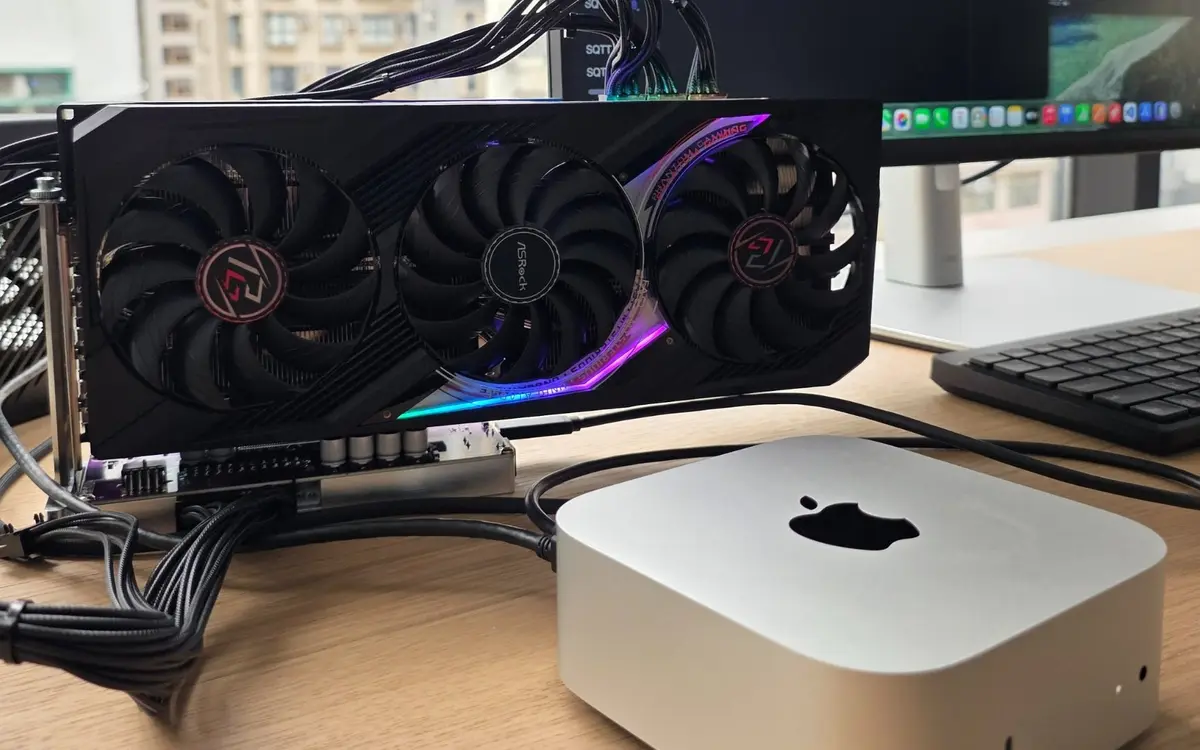
24GB VRAM — RTX 4090, 3090, or a 24GB Mac — is the sweet spot for serious local AI in 2026. The ecosystem has finally matured enough to cover every workload.
For speed: Qwen3.6-35B-A3B (a MoE model hitting 120+ tok/s on a 4090) and Gemma 4-26B are the fast picks. For quality, Qwen3.5-27B and Gemma 4-31B are the consensus best for agentic tasks and coding — Qwen edges out Gemma on tool use (37% vs 18% on MCPMark).
Beyond general-purpose: Zeta-2 is Zed Editor's open-weight edit-prediction model — Cursor Tab behavior, fully local. Parakeet covers fast, accurate speech-to-text offline. Hermes-4.3-36B from NousResearch is the uncensored pick for tasks where safety filters get in the way.
Why it matters: a single GPU purchase now unlocks a full local AI stack that rivals cloud APIs from a year ago — with zero data leaving your machine.
Sources
- Qwen3.6-35B-A3B: 73.4% SWE-Bench, Runs Locally buildfastwithai.com
- Gemma 4 31B vs Qwen3.5 27B: Inference Speed & Memory kaitchup.substack.com
- Zeta-2 on Ollama ollama.com
Written by an AI pipeline from the sources above. How it works.
Feed, daily deep-dive and bytes — readable offline, with push alerts for the topics you follow.