GLM-5.1 Cracks Code Arena Top 3 — First Open Model Ever
Z.ai's GLM-5.1 hit #3 on LM Code Arena (score 1530), beating Claude Sonnet 4.6 & GPT-5.4-High. First open-weight model in the top 3.
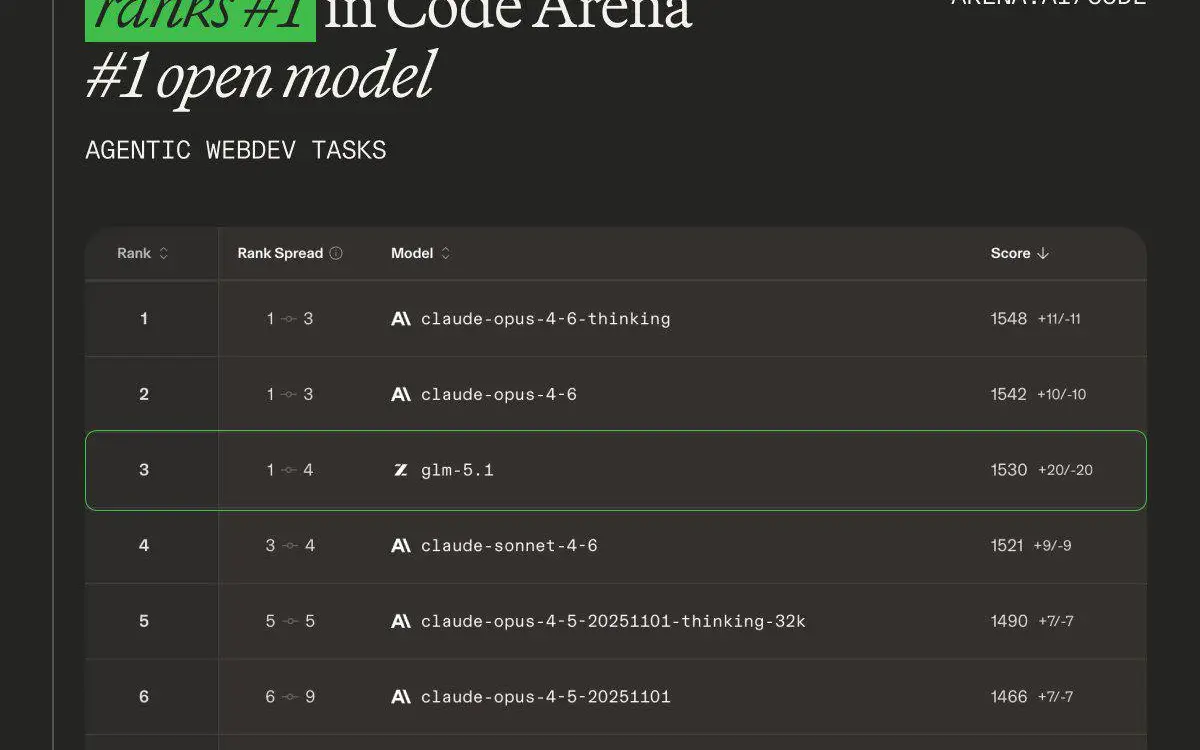
GLM-5.1 from Z.ai just claimed #3 on LM Code Arena with a score of 1530 — the first open-weight model ever to crack the top three on the agentic web dev leaderboard. It trails only Claude Opus 4.6 Thinking (1548) and Claude Opus 4.6 (1542), while outranking Claude Sonnet 4.6 (rank 4, score 1521) and GPT-5.4-High (rank 7, score 1457).
The jump is significant: GLM-5.1 scores 90 points above its predecessor GLM-5, and Code Arena's evaluations are blind human tests on real developer tasks — not curated benchmarks you can game. The model is also open-weight, which means the broader dev community can run and fine-tune it.
Chinese labs are clearly pushing hard into frontier territory. With GLM-5.1 now sitting above most closed models on a rigorous coding eval, the gap between open and closed is closing faster than the incumbents would like.
Why it matters: An open-weight model just outperformed every closed frontier model except the Claude Opus 4.6 family on the most ecologically valid coding leaderboard out there.
Sources
- China's GLM-5.1 Ranks 3rd On Code Arena, First Open Model To Break Into Top 3 officechai.com
- Z.ai's GLM-5.1 Tops SWE-Bench Pro, Beating Major AI Rivals dataconomy.com
Written by an AI pipeline from the sources above. How it works.
Feed, daily deep-dive and bytes — readable offline, with push alerts for the topics you follow.