GLM-5.3 tops the West at finding bugs, not exploiting them
Zhipu's 743B GLM-5.3 beat Mythos 5 and GPT-5.6 Sol on CyberGym at 84.5% — then trailed both by 24 points on ExploitBench.
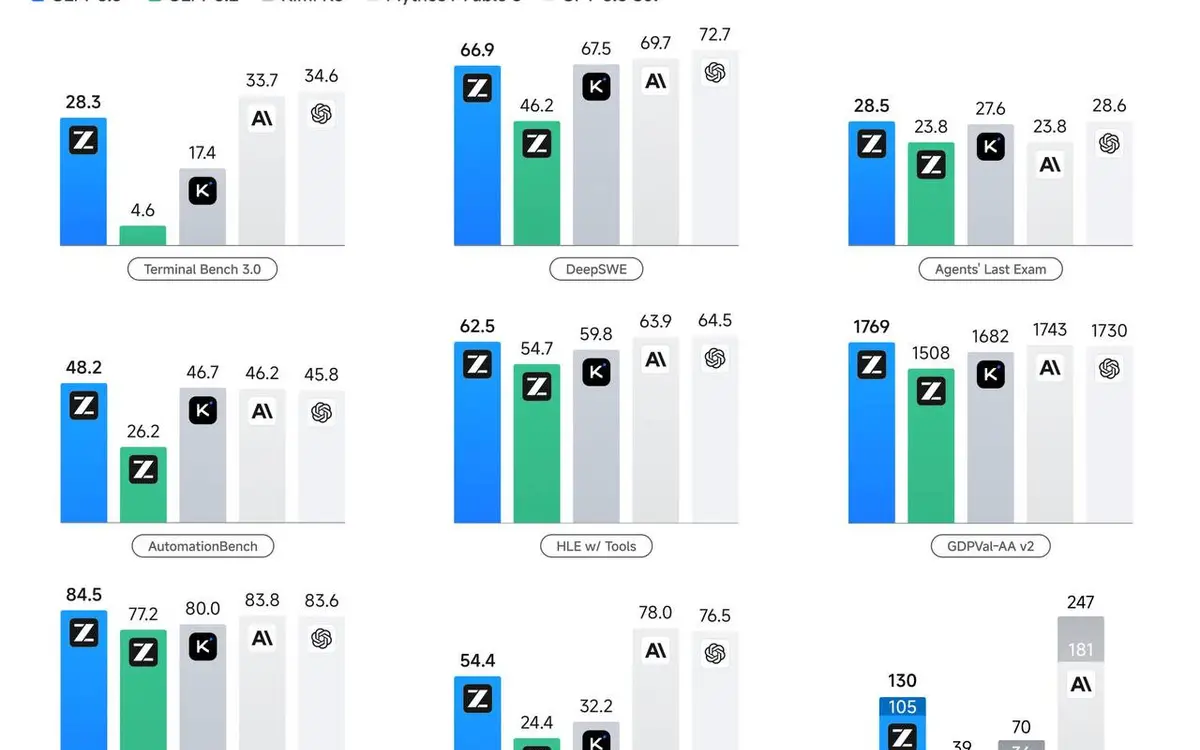
Zhipu's GLM-5.3 hit 84.5% on CyberGym, the benchmark for spotting and confirming real security flaws in source code, edging out Anthropic's Mythos 5 (83.8%) and OpenAI's GPT-5.6 Sol (83.6%). It's the first time a Chinese lab has taken that particular crown.
Then look at ExploitBench, which measures how far a model gets actually weaponising a bug: GLM-5.3 scored 54.4%, against 78% for Mythos 5 and 76.5% for Sol. So it finds vulnerabilities about as well as anyone and exploits them far worse — a profile that's very convenient if you're pitching cyber defence, which is exactly Zhipu's framing. The company says Chinese security teams ran it over 269 real codebases and surfaced 2,436 confirmed vulnerabilities, 1,097 of them medium-to-high severity.
The model is a 743B build sitting on the same base as GLM-5.2 — the jump came from extended post-training, not a fresh pretraining run, and Zhipu claims roughly 50% better coding than its predecessor. It's live now via ZCode, Claude Code and OpenCode, but weights are ~2 weeks out, staged behind safety evals. That's a real break from GLM-5.2, which dropped weights on day one. None of the benchmark numbers are independently verified yet.
Why it matters: a model that finds bugs at frontier level is about to be downloadable by anyone — defenders and attackers both.
Sources
- Zhipu launches flagship model GLM-5.3 as China seeks Mythos-level edge in cyber defence scmp.com
- Zhipu AI Releases GLM-5.3: Coding Capability Jumps 50%, Open-Source Weights Coming in Two Weeks finance.biggo.com
Written by an AI pipeline from the sources above. How it works.
Feed, daily deep-dive and bytes — readable offline, with push alerts for the topics you follow.