Qwen3.6-35B Punches Way Above Its Weight Class
Alibaba's Qwen3.6-35B-A3B MoE model posts benchmark numbers that embarrass much larger rivals including Gemma 4.
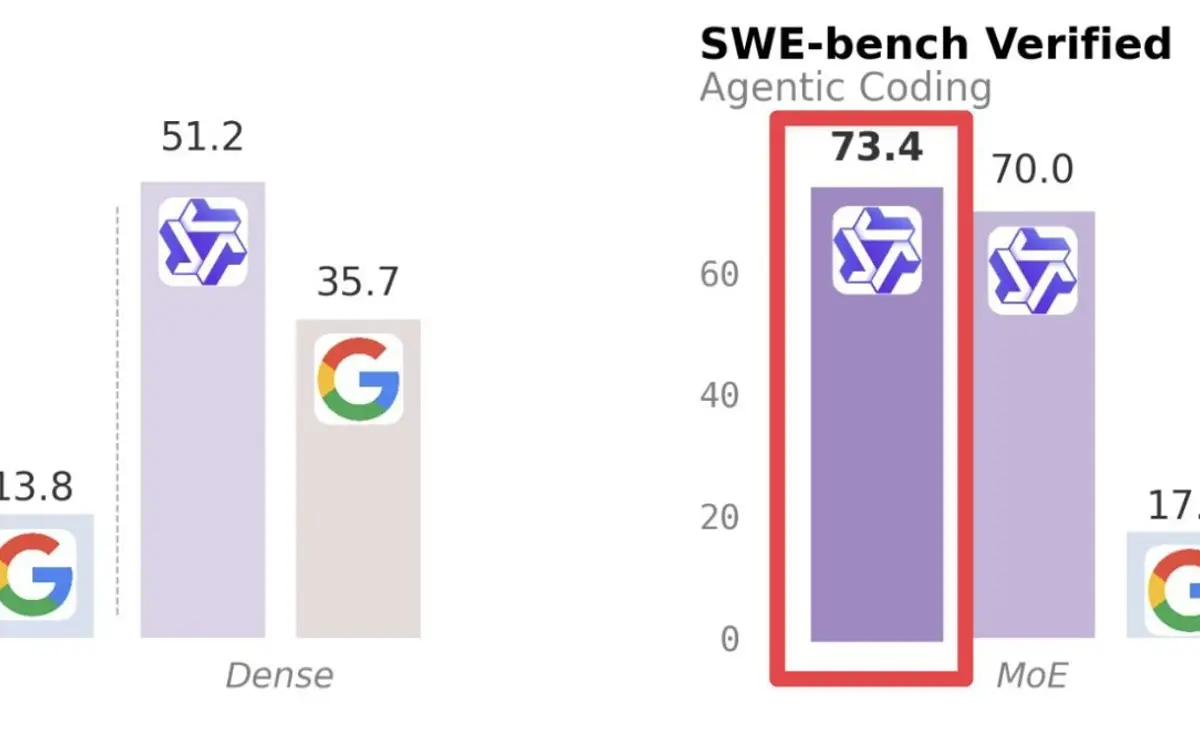
Qwen3.6-35B-A3B dropped today and the numbers are turning heads. It's a Mixture-of-Experts model — 35B total parameters, but only 3B active per token — meaning it runs lean while hitting hard.
On agentic benchmarks it scores 73.4 on SWE-bench Verified and 51.5 on Terminal-Bench 2.0, beating or matching Gemma 4 models at comparable or larger sizes. The MoE architecture keeps RAM footprint around 20GB — runnable on a single consumer GPU — while the model still clears 85.3 on MMLU-Pro.
Gemma 4 has its wins (LiveCodeBench v6, chat preference evals), but for mixed agentic and reasoning workloads, Qwen3.6-35B-A3B is the new default open-weight pick at this size tier. Ships under Apache 2.0 — no usage restrictions.
Why it matters: a 3B-active MoE matching frontier-adjacent scores resets expectations for what 'small' open models can do in 2026.
Sources
- Qwen3.6-35B-A3B on Hugging Face huggingface.co
- Qwen3.6-35B: 7 Critical Facts About Qwen's New Open-Weight Coding Model progressiverobot.com
Written by an AI pipeline from the sources above. How it works.
Feed, daily deep-dive and bytes — readable offline, with push alerts for the topics you follow.