Claude Mythos Benchmarks Drop: 10-15% Real-World Edge Over Opus 4.7
Anthropic's Mythos clears Opus 4.7 on SWE-bench, GPQA, and math — but it's not yours to use yet.
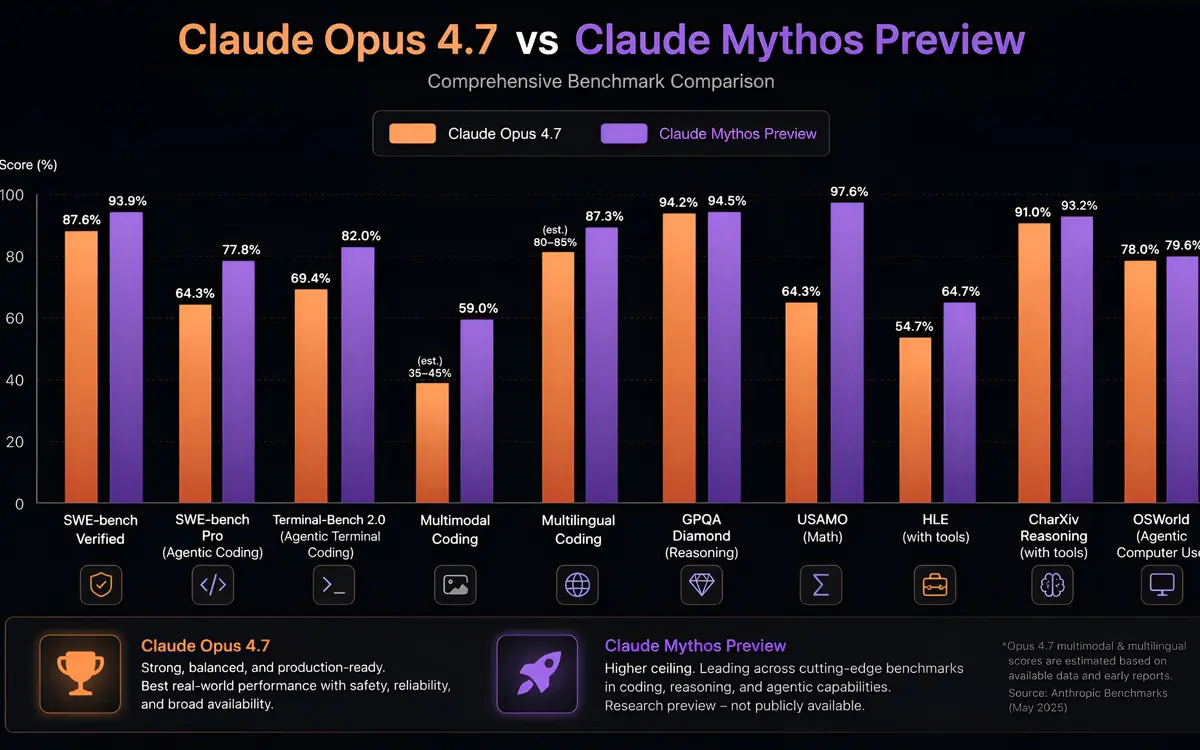
Anthropic's Claude Mythos is pulling 10–15% ahead of Opus 4.7 in real-world evals, with a benchmark gap that widens the further up you push it.
On SWE-bench Verified, Mythos lands in the mid-to-high 80s vs Opus 4.6's low-to-mid 70s — roughly a 12–15 point jump. GPQA Diamond reasoning climbs into the low 80s, clearing the 74–79% plateau where frontier models have stalled for months. The starkest gap is math: USAMO 2026 scores of 97.6% vs 42.3% for Opus 4.6.
Mythos isn't a model you can ship with — at least not yet. Previewed April 7, 2026, it's restricted to 11 orgs under Project Glasswing, Anthropic's cybersecurity initiative. Internal testing reportedly saw it autonomously exploit zero-days across every major OS and browser. No public timeline has been announced.
Opus 4.7, meanwhile, is still expected to drop soon and will likely serve as the public flagship — Mythos is playing a different game entirely.
Why it matters: Anthropic is quietly spinning up a new model tier above the 4.x line, and Mythos benchmarks suggest the gap won't be easy for anyone to close fast.
Sources
- Anthropic debuts preview of powerful new AI model Mythos techcrunch.com
- Exclusive: Anthropic 'Mythos' AI model — a step change in capabilities fortune.com
- Claude Mythos vs Claude Opus 4.6: Capability Comparison mindstudio.ai
Written by an AI pipeline from the sources above. How it works.
Feed, daily deep-dive and bytes — readable offline, with push alerts for the topics you follow.