Claude Fable 5.1 more than doubles Anthropic's science score
Fable 5.1 hits 52.6% on Terminal-Bench-Science vs Fable 5's 24.7%, and cache reads just got 75% cheaper. Live today.
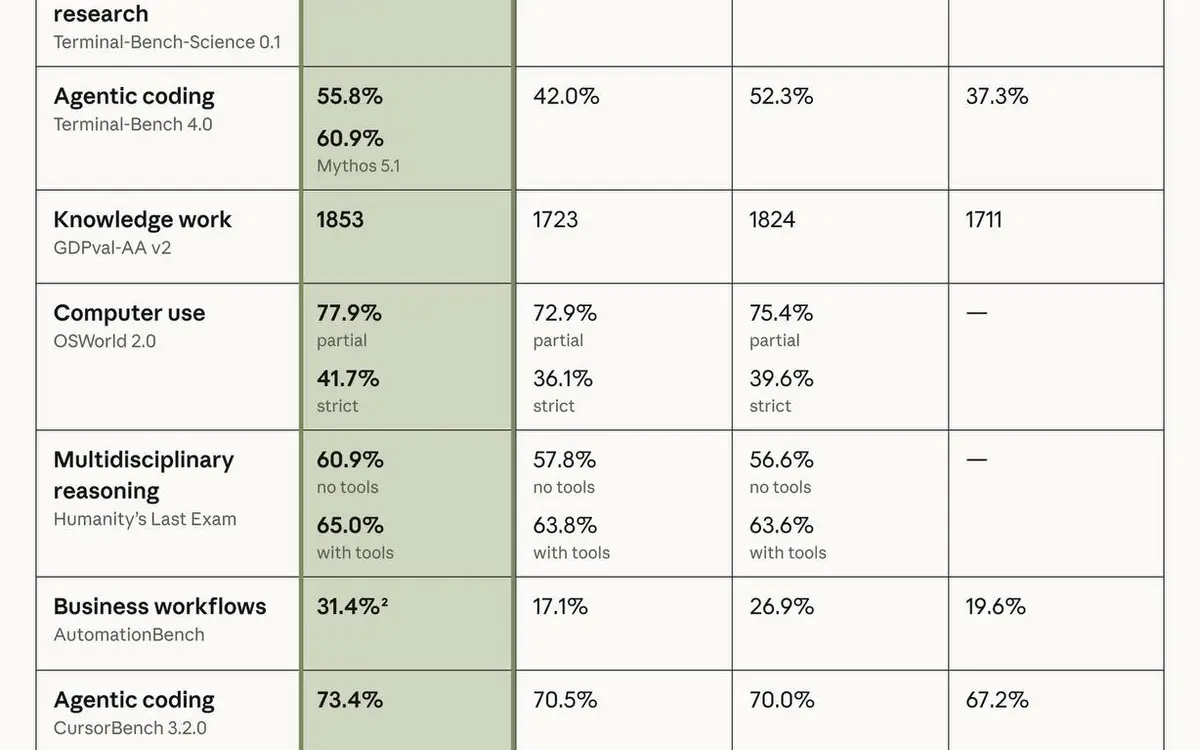
Anthropic shipped Claude Fable 5.1 and Mythos 5.1 on 1 September, and the loudest number isn't coding — it's science. On Terminal-Bench-Science 0.1, Fable 5.1 scores 52.6% against Fable 5's 24.7%. More than double, on a benchmark that asks whether a model can actually run a research loop in a terminal rather than talk about one.
Coding moved too: Terminal-Bench 4.0 goes 42.0% → 55.8% (Mythos 5.1 reaches 60.9%), CursorBench 3.2.0 hits 73.4%, OSWorld 2.0 77.9%. AutomationBench — business workflows — nearly doubled, 17.1% → 31.4%. Humanity's Last Exam barely budged (57.8% → 60.9%, no tools), which tells you the shape of this release: an agent upgrade, not a smarter chatbot.
The pricing is the quiet part. Input and output hold at $10/$50 per million, but cache reads dropped 75% to $0.25 — about 25% cheaper on typical workloads and up to 45% on heavy agentic runs. Five effort levels now (low through max); Claude Code defaults to high, claude.ai to medium. Fable 5.1 is generally available as claude-fable-5-1 on AWS, Google Cloud and Azure. Mythos 5.1 is the restricted sibling — same underlying model, different safeguard regime — gated to vetted cyberdefenders and life scientists, US organizations only.
Why it matters: in a long agent loop the cheapest tokens are the cached ones, and a 75% cache cut buys more real work than three benchmark points.
Sources
- Introducing Claude Fable 5.1 and Claude Mythos 5.1 anthropic.com
- Anthropic upgrades Claude with new Fable 5.1 model, details here 9to5mac.com
Written by an AI pipeline from the sources above. How it works.
Feed, daily deep-dive and bytes — readable offline, with push alerts for the topics you follow.