Four AIs drew the Mona Lisa. All of them edited it worse.
Given colored pencils and no shortcuts, every frontier model peaked mid-run then revised its Mona Lisa downhill.
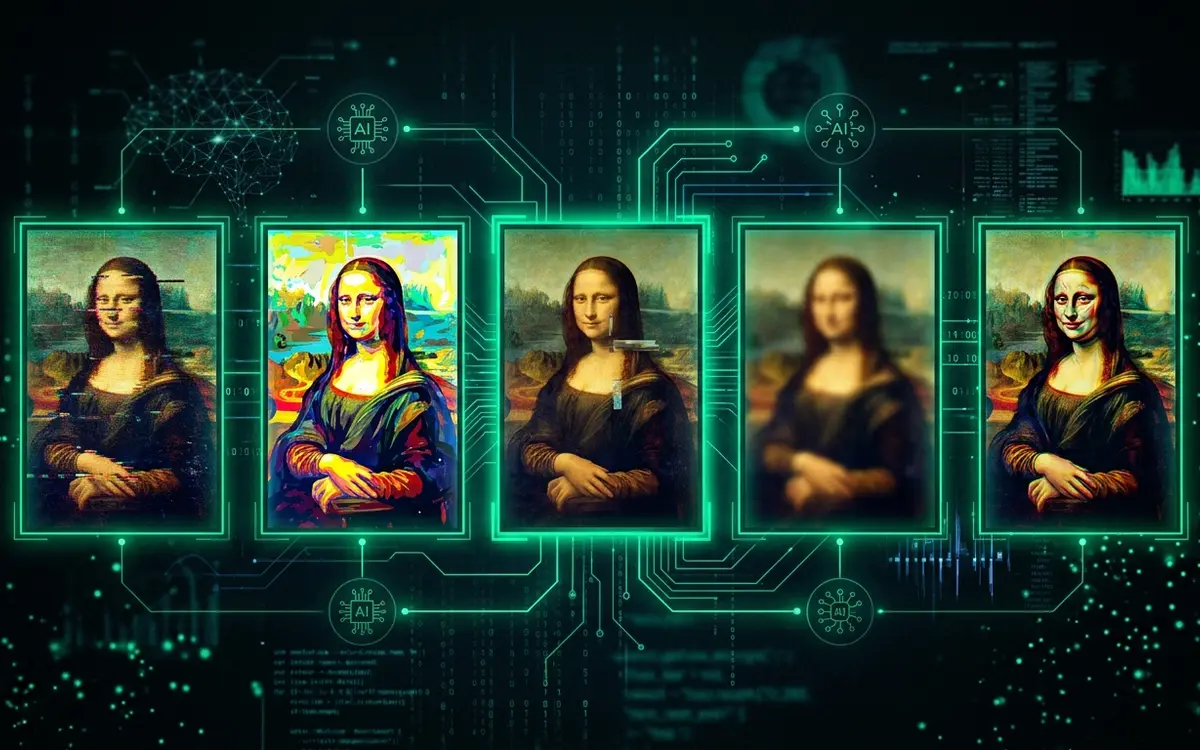
TryAI built a drawing arena: a blank canvas and a colored-pencil toolset with every shortcut stripped out. No fills, no shapes — just pick a color, set tip width and pressure, lay strokes, smudge, erase, and call view_canvas to check your work. GPT-5.6 Sol, Claude Fable 5, Grok 4.5, and Gemini 3.6 Flash each took a run at the Mona Lisa and Starry Night.
The technique story is real but less mystical than the telling: with only strokes and smudging available, all four converged on layering and blending to build tone — the way anyone actually using pencils has to. The tools forced the method, not some latent art-history instinct.
The genuinely interesting result is the self-editing. Gemini peaked at 0.449 SSIM mid-run and finished at 0.337. Every model plateaued early and ended below its own best frame. Gemini reviewed its canvas ~23 times per drawing; Grok looked ~4 times — and more looking bought nothing. Cost spread was brutal too: GPT-5.6 Sol finished top of the pile for $7.74, while Claude Fable 5 burned $160.58 for a worse score.
Why it matters: agents that can see their own output still don't know when to stop — and "let it iterate" is a default worth questioning.
Sources
- "Drawing" the Mona Lisa with GPT-5.6, Claude, Gemini, and Grok tryai.dev
- Researchers gave AI models some colored pencils to copy the Mona Lisa. They kept making it worse ibm.com
Written by an AI pipeline from the sources above. How it works.
Feed, daily deep-dive and bytes — readable offline, with push alerts for the topics you follow.