Alibaba open-sources Qwen3.6-35B — punches way above its weight
35B MoE model, only 3B active at inference — beats Gemma 4-31B on coding, matches Claude Sonnet 4.5 on vision.
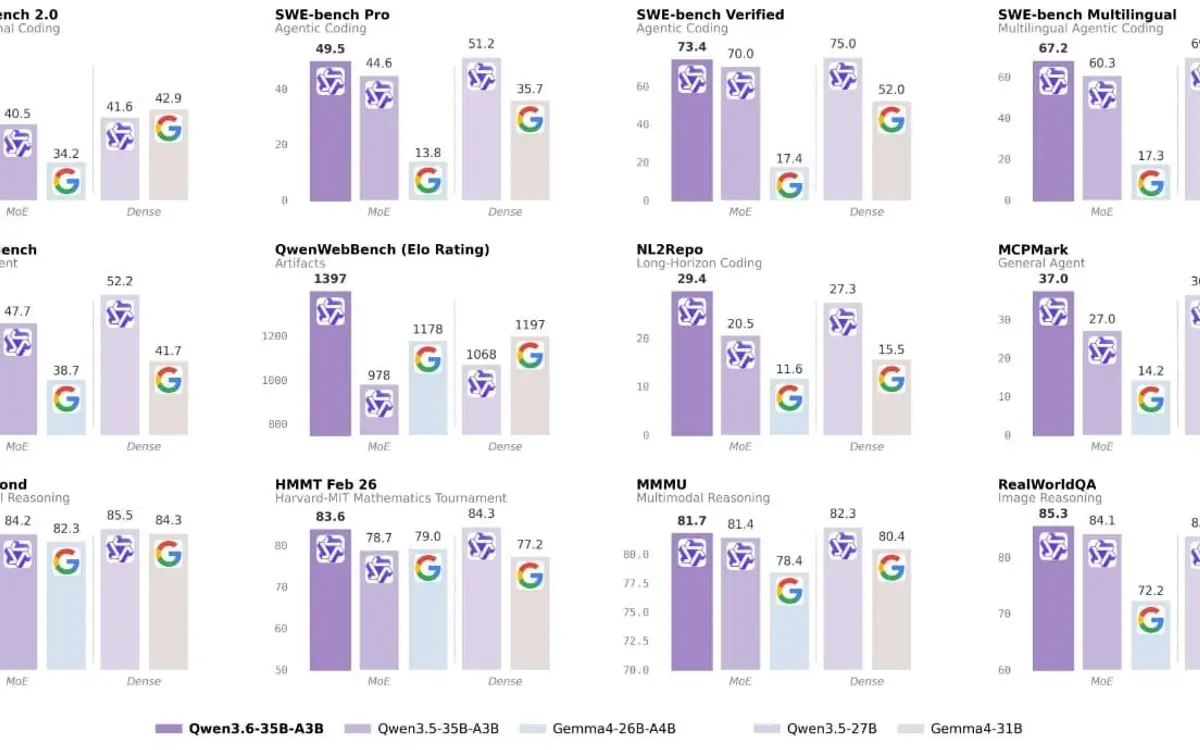
Alibaba dropped Qwen3.6-35B-A3B today under Apache 2.0 — a sparse Mixture-of-Experts model with 35 billion total parameters but only 3 billion active per token. Same inference cost as a small model, capacity of a large one.
On agentic coding it's not close: SWE-bench Verified scores 73.4 vs Gemma 4-31B's 52.0, Terminal-Bench 2.0 hits 51.5 vs 42.9, SWE-bench Pro clocks 49.5 vs 35.7. Multimodal performance matches Claude Sonnet 4.5 on most vision-language tasks and edges ahead on spatial reasoning.
Full weights ship on Hugging Face with a native 262K token context (extendable to 1M), plus built-in thinking and non-thinking modes — no license restrictions on commercial use.
Why it matters: open-source MoE efficiency is closing the gap fast — frontier-grade agentic coding at 3B active-param cost, self-hostable.
Sources
Primary: the company, paper or repository
- Qwen/Qwen3.6-35B-A3B · Hugging Face huggingface.co
Independent coverage
Written by an AI pipeline from the sources above. Methodology · Report an error
The stories that matter for people who build with AI, with the source for every claim. Free, no spam.
Feed, daily deep-dive and bytes — readable offline, with push alerts for the topics you follow.