Alibaba's 2.4T-param Qwen3.8-Max goes after Fable 5
Alibaba shipped its biggest model yet — 2.4T params, 1M context, frontier-tier coding scores. Open weights land next week.
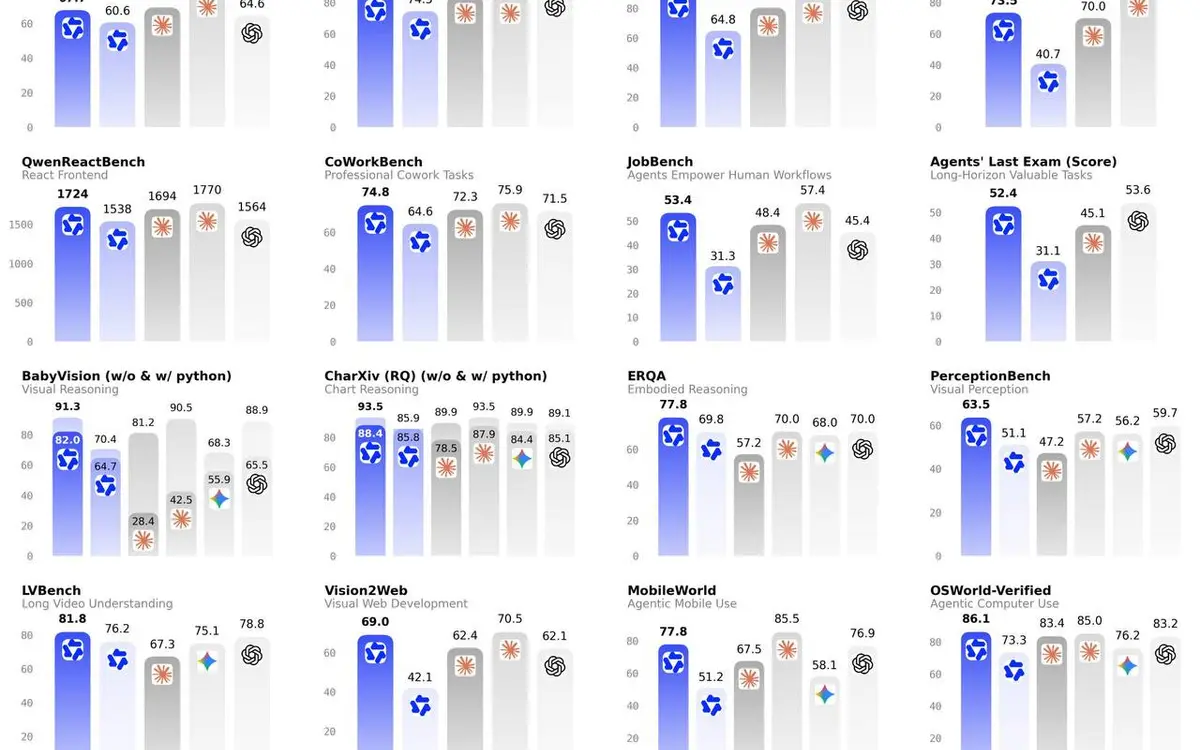
Alibaba dropped Qwen3.8-Max on Aug 3 — a 2.4 trillion parameter mixture-of-experts model that activates only 95B params per query, takes text, images and video, and handles a 1M-token context (991K in, 131K out).
The benchmark table is the real story. Terminal-Bench 2.1: 86.6, just under GPT-5.6 Sol's 88.8 and ahead of Claude Opus 4.8's 84.6. SWE-bench Pro: 67.7, up from 60.6 on Qwen3.7-Max. FrontierSWE jumped from 40.7 to 73.5 — the biggest single-generation leap on the sheet. On OSWorld-Verified computer-use it posts 86.1, edging out both GPT-5.6 Sol Max and Fable 5. It's now the top-ranked Chinese model for text on Arena.AI and #2 globally for vision. Alibaba stock popped ~7% in Hong Kong.
One correction to the chatter making the rounds: there's no "10+ days of autonomous coding" claim anywhere in Alibaba's materials — that number appears to be invented. What is confirmed: open weights ship next week, alongside a Qwen3.8-27B checkpoint aimed at on-prem deployment.
Why it matters: a frontier-adjacent model with open weights a week later collapses the gap between "best available" and "runs on your own hardware."
Sources
Independent coverage
- Alibaba Qwen Releases Qwen3.8-Max: A 2.4 Trillion Parameter MoE Model marktechpost.com
- Qwen3.8-Max arrives with a bold claim: it outperforms GPT-5.6 Sol Max and Fable 5 on agentic computer use venturebeat.com
- Alibaba debuts Qwen3.8-Max model with 2.4T parameters siliconangle.com
Written by an AI pipeline from the sources above. Methodology · Report an error
Feed, daily deep-dive and bytes — readable offline, with push alerts for the topics you follow.