DeepSeek's 'smallest' new model is 552B — and it beats V4 Pro
DeepSeek open-sourced V4.1 Flash under MIT: a 552B multimodal MoE running just 8-16B active params that it says tops its own V4 Pro.
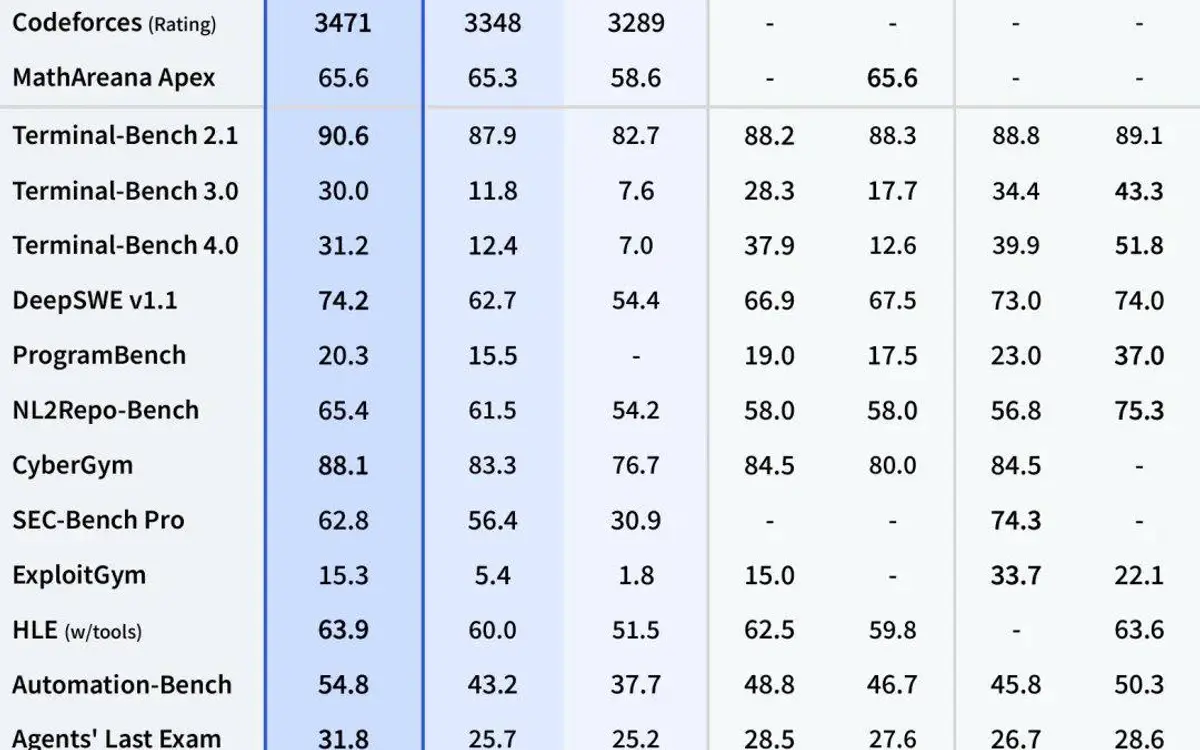
DeepSeek-V4.1-Flash landed on Hugging Face today under an MIT license. It is the smallest model in DeepSeek's new architecture family, and it still has 552B parameters. What keeps it cheap is a new Causal Encoder-Decoder (CED) layout: 40 layers split into a 20-layer encoder and a 20-layer decoder. Only 8B params fire per token on input and 16B on output, which suits agent workloads that read far more than they write. It also understands images natively and handles 1M-token context.
The efficiency numbers are the real story. The global KV cache is down to 890 bytes per token, about a quarter of V4 Flash, thanks to FP4 caching and KV sharing across layers. It was pretrained on 45T multimodal tokens and got heavier RL post-training. It scores 74.2 on DeepSWE v1.1 (up from 54.4 for V4 Flash), 90.9 on GPQA Diamond and a 3471 Codeforces rating. DeepSeek claims it beats V4 Pro on performance, cost and speed, and it's putting its API where its mouth is: from Sept 14, calls to deepseek-v4-pro get routed to Flash and billed at Flash prices until V4.1 Pro ships.
Why it matters: an open-weights frontier-class model that runs only 8B params per input token makes long-context agents much cheaper to run, including on your own hardware.
Sources
Primary: the company, paper or repository
- deepseek-ai/DeepSeek-V4.1-Flash · Hugging Face huggingface.co
Independent coverage
- Change Log | DeepSeek API Docs api-docs.deepseek.com
Written by an AI pipeline from the sources above. Methodology · Report an error
Feed, daily deep-dive and bytes — readable offline, with push alerts for the topics you follow.