Grok 4.5 tops pro-work benchmarks at a bargain $2/M
SpaceXAI's Grok 4.5 beats GPT-5.5 and Claude Opus 4.8 on real professional tasks — for just $2 per million input tokens.
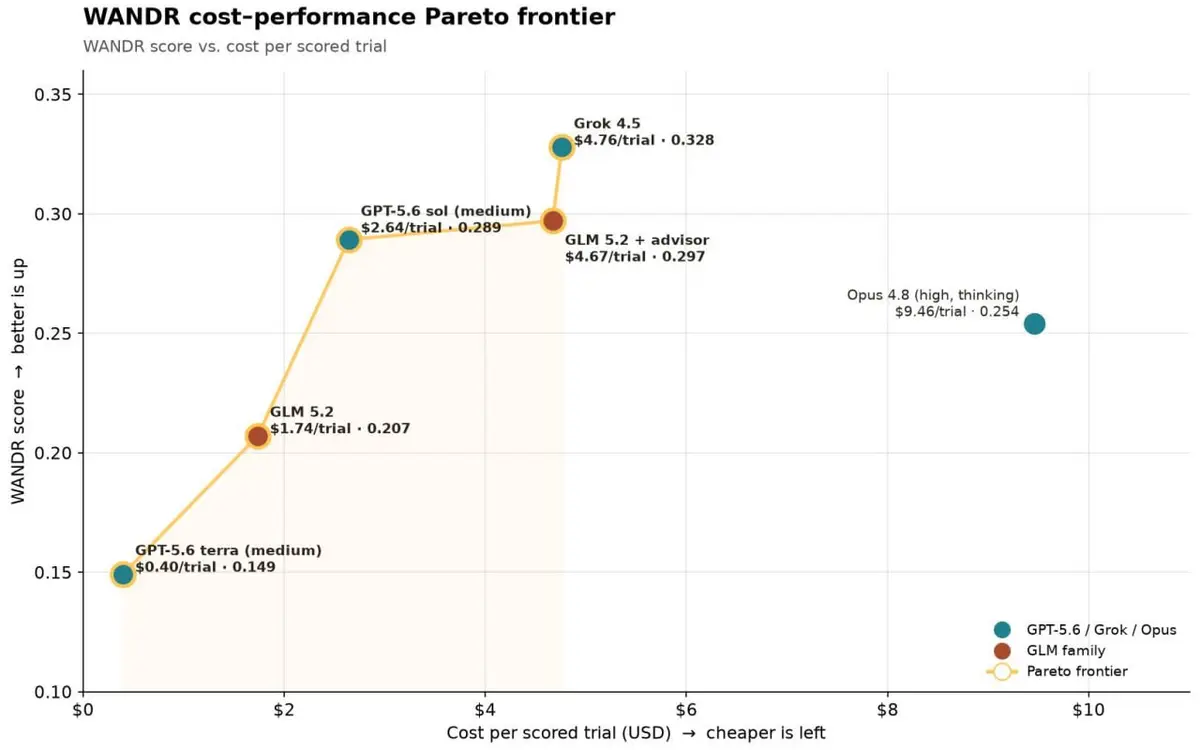
Grok 4.5, SpaceXAI's newest model, just posted the best score yet on Snorkel's GDPVal+ suite of ~2,000 real professional-work tasks — a 29% mean pass rate, ahead of GPT-5.5 (22%) and Claude Opus 4.8 (21%). It ships with a 500K-token context window and was trained alongside Cursor for coding and agentic work.
The kicker is the price: $2 per million input tokens. That undercuts most frontier proprietary models and puts Grok in the same aggressive-pricing conversation as open-weight challengers like Z.ai's GLM-5.2, the MIT-licensed 744B MoE model that's been beating GPT-5.5 at roughly a sixth of the cost.
The pattern is hard to miss: frontier-level performance is decoupling from frontier-level pricing. Closed models are chasing the cost curve that open-weight labs set, and the gap between "best" and "cheapest good enough" keeps shrinking.
Why it matters: when the top-scoring model is also one of the cheapest, model choice stops being about capability and starts being about lock-in.
Sources
Independent coverage
- SpaceXAI Releases Grok 4.5 at $2/M Input marktechpost.com
- Grok 4.5 Testing Results vs GPT-5.5 & Claude Opus 4.8 snorkel.ai
Written by an AI pipeline from the sources above. Methodology · Report an error
The stories that matter for people who build with AI, with the source for every claim. Free, no spam.
Feed, daily deep-dive and bytes — readable offline, with push alerts for the topics you follow.