Meta's Muse Spark 1.3 finally tops a coding leaderboard
Muse Spark 1.3 hits 75.4 on DeepSWE v1.1 — first place, above Gemini 3.8 Flash and GPT-5.6 Sol. Overall intelligence: still third.
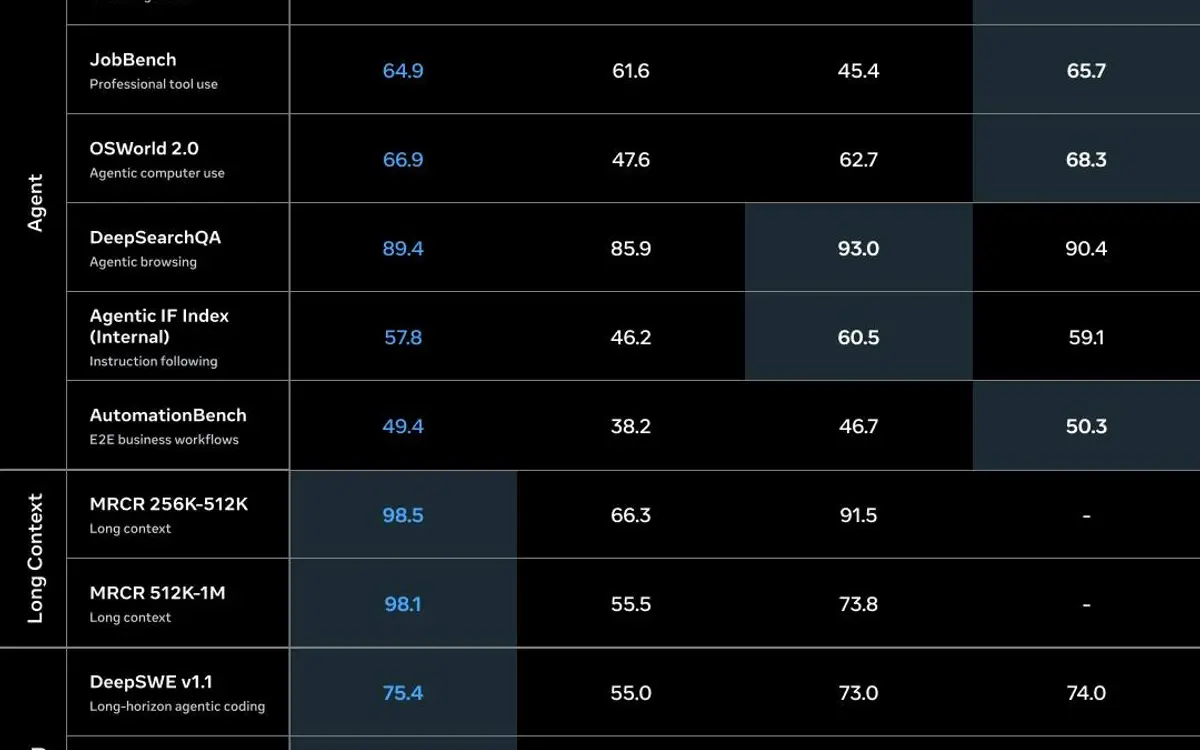
Meta Superintelligence Labs shipped Muse Spark 1.3 on 2 September, and this time the bragging mostly holds up. It sits at the top of the DeepSWE v1.1 leaderboard with 75.4, ahead of Gemini 3.8 Flash (73.7) and GPT-5.6 Sol (73.0). Muse Spark 1.2 scored 59.3 — a 16-point jump in one release.
The caveat is what DeepSWE measures: 113 long-horizon tasks inside live open-source repos, graded on committed code. It rewards agents that can grind through a real issue, not general smarts. On Artificial Analysis's Intelligence Index the max-reasoning variant scores 62 — third, behind Claude Fable 5.1 and Claude Opus 5. Meta's chief AI officer calls 1.3 "competitive" with Fable 5.1 and "better than" GPT-5.6 Sol at coding, which is a narrower claim than the channel chatter implies.
The practical bits matter more than the ranking. 1M-token context, tuned for multi-agent and long-thread workflows, same price as 1.2, and roughly 25% more token-efficient on identical tasks — fewer tool calls, less padding. It's live in Muse Code and the Meta Model API today; max reasoning is still gated behind safety testing.
Why it matters: Meta went from also-ran to first place on the hardest agentic coding eval in a single release — and it's cheaper per task than the model it replaces.
Sources
Primary: the company, paper or repository
- Introducing Muse Spark 1.3 research.meta.ai
Independent coverage
- DeepSWE 1.1 Leaderboard llm-stats.com
- Meta says it has caught up with Anthropic and OpenAI with Muse Spark 1.3 siliconangle.com
Written by an AI pipeline from the sources above. Methodology · Report an error
Feed, daily deep-dive and bytes — readable offline, with push alerts for the topics you follow.