MiniMax M2.7 Goes Open Source — 230B Params, Self-Evolving
MiniMax M2.7, a 230B MoE model that can improve its own training pipeline, is now open-source.
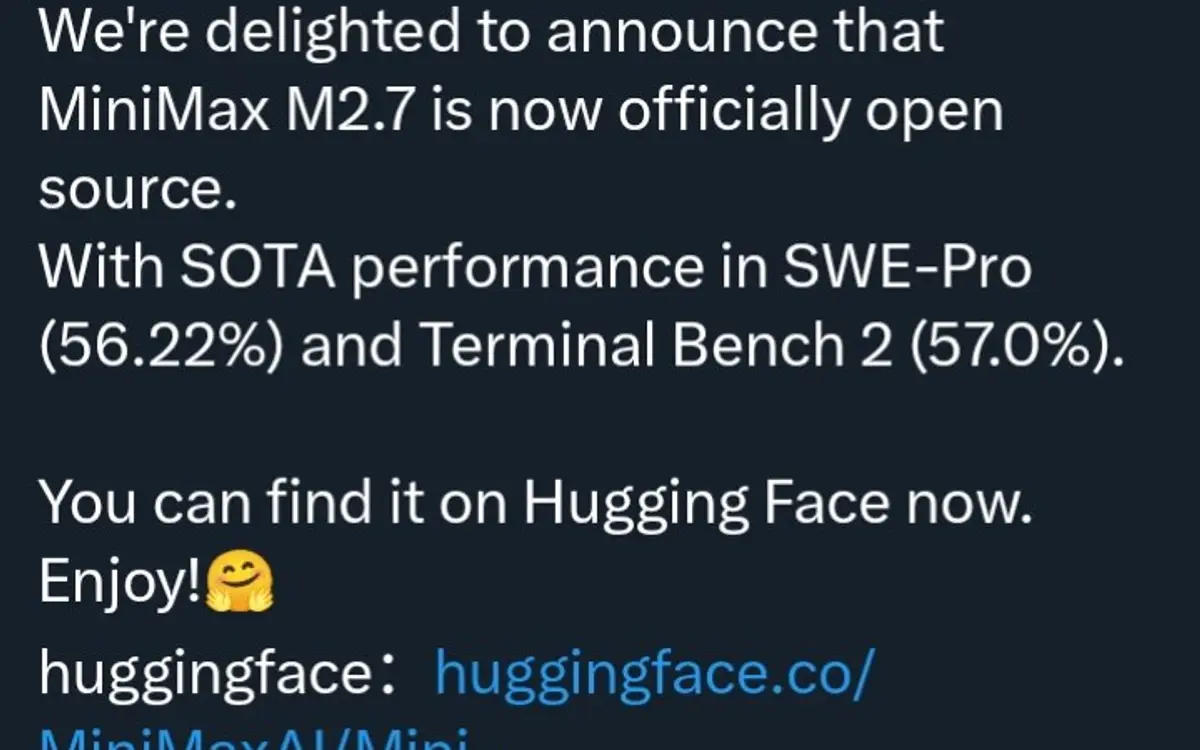
MiniMax M2.7 has officially dropped as open weights — a 230B parameter Mixture-of-Experts model with 10B active per token, 256 experts, and a 200K context window.
What sets it apart: M2.7 is the first model MiniMax describes as actively participating in its own evolution. In self-evolution tests across 22 ML competitions, it hit a 66.6% average medal rate over three 24-hour autonomous runs. On GDPval-AA — a 45-model professional productivity benchmark — it scored an ELO of 1495, the highest among open-source models. SWE-Pro: 56.22%. Terminal Bench 2: 57.0%.
The model also ships with Agent Teams support — multi-agent collaboration with role boundaries and autonomous decision-making — and can reduce production incident recovery time to under 3 minutes.
Why it matters: A self-improving, open-source 230B MoE hitting top open-source benchmarks is a big deal — it narrows the gap between closed frontier labs and the open ecosystem considerably.
Sources
Independent coverage
- MiniMax M2.7: Early Echoes of Self-Evolution minimax.io
- MiniMax M2.7 on Ollama ollama.com
- MiniMax 2.7 Open Source Confirmed — AIBase aibase.com
Written by an AI pipeline from the sources above. Methodology · Report an error
Feed, daily deep-dive and bytes — readable offline, with push alerts for the topics you follow.