Nanbeige's open 33B model beats Qwen on agentic coding
BOSS Zhipin's AI lab released Nanbeige4.3-33B under Apache 2.0. It reports 80.9 on Terminal-Bench 2.1 and has a 512K context.
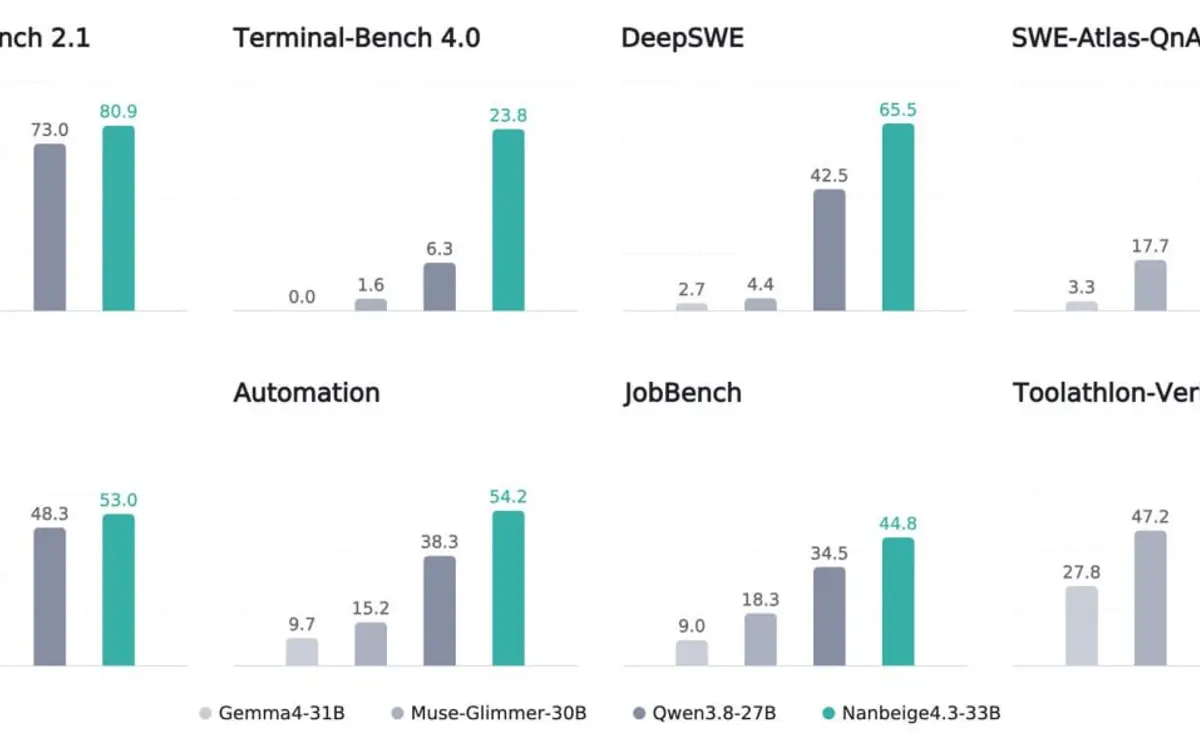
Nanbeige4.3-33B comes from Nanbeige LLM Lab, the AI team at Chinese job site BOSS Zhipin. The lab reports 65.5 on DeepSWE, well ahead of Qwen3.8-27B's 42.5. On Terminal-Bench 2.1 it reports 80.9 against Qwen's 73.0, Muse-Glimmer-30B's 61.8 and Gemma4-31B's 47.2. The weights went up on Hugging Face on 24 Oct under Apache 2.0.
This is a dense 33B model, not a mixture-of-experts, with a native 512K-token context. The lab says it is strongest at office-style agent work: 54.2 on Automation Bench against Qwen's 38.3, and 44.8 on JobBench against 34.5. It does not win everything. Qwen3.8-27B leads narrowly on SWE-Bench Pro (61.7 vs 60.3) and GDPval, and Gemma4-31B leads on GPQA Diamond (91.3 vs 89.5). All of these numbers come from the lab itself, and no independent evaluations have been published yet.
The bigger plan: the 33B model is a teacher. Nanbeige says it will distil it into smaller models, starting with Nanbeige4.3-3B. The lab is best known for 3B models, and that one has no release date yet.
Why it matters: a recruitment company now has an open model that competes with Qwen and Gemma on agent work, and you can run it commercially.
Sources
Primary: the company, paper or repository
- Nanbeige4.3-33B model card huggingface.co
Independent coverage
- Nanbeige4.3-33B: Apache 2.0 dense agentic coding model with 512K context and benchmarks datastudios.org
Written by an AI pipeline from the sources above. Methodology · Report an error
The stories that matter for people who build with AI, with the source for every claim. Free, no spam.
Feed, daily deep-dive and bytes — readable offline, with push alerts for the topics you follow.