NVIDIA's Nemotron 3.5 Super VL: 120B open model, only 12B awake
NVIDIA's new open multimodal model reads text, images, docs and video and claims 5x the throughput of open models its size.
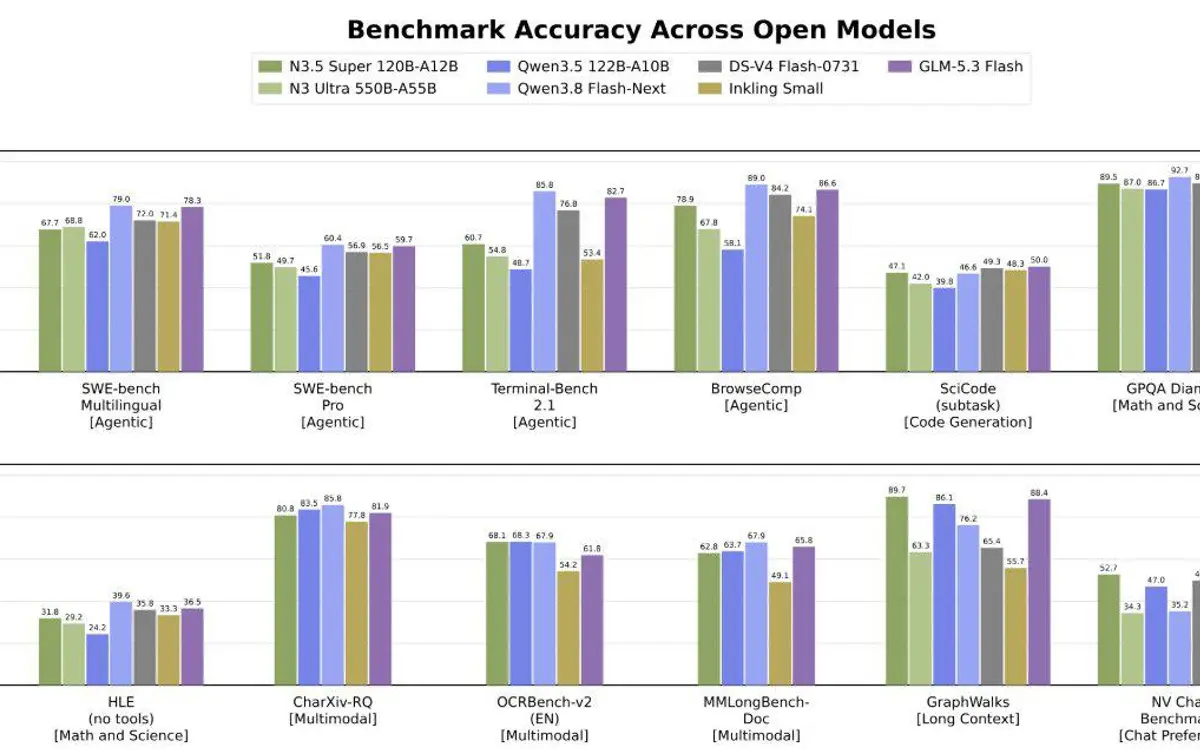
NVIDIA says Nemotron 3.5 Super VL matches its largest reasoning model on multimodal agent tasks at about one-fifth the parameters. It's a 120B mixture-of-experts model that activates only 12B parameters per token. It handles text, images, documents and video (mp4 clips up to 2 minutes) in one system, with up to a 1M-token context. NVIDIA calls it the fastest open agentic model in its class, with up to 5x the throughput of open models of similar size on a single GPU.
Under the hood it mixes Mamba-2 and Transformer layers with MoE routing and a C-RADIO vision encoder. It was distilled from Nemotron 3 Ultra and trained on about 26T tokens. NVIDIA is releasing far more than the weights: base, post-trained and NVFP4 checkpoints, training recipes, datasets and RL environments, all under the commercially usable OpenMDW-1.1 license. NVIDIA reports 71.1 on SWE-bench Verified, 89.5 on GPQA-Diamond and 80.8% on CharXiv chart reasoning. Almost every number so far comes from NVIDIA itself. It's live on Hugging Face, OpenRouter, ModelScope and NVIDIA NIM.
Two smaller Bolt models launched alongside it for running on your own machine. Bolt 74B-A9B uses native 2-bit quantization to fit in 24GB, and a 4GB E4B version arrives on 23 Oct. Atlassian, CrowdStrike, Perplexity and Salesforce are among the early integrators.
Why it matters: NVIDIA keeps releasing fully open, agent-ready models that run fast on its own chips, which makes it harder to justify paying for a closed model to read documents.
Sources
Primary: the company, paper or repository
- NVIDIA Expands Nemotron Family With Highest Efficiency Super VL and Bolt Models blogs.nvidia.com
- nvidia/NVIDIA-Nemotron-3.5-Super-VL-120B-A12B-BF16 huggingface.co
Independent coverage
Written by an AI pipeline from the sources above. Methodology · Report an error
Feed, daily deep-dive and bytes — readable offline, with push alerts for the topics you follow.