The $1K local AI stack that actually runs in 2026
24GB GPU or Mac gets you a full local AI stack — fast inference, tab completion, speech-to-text, and no censorship.
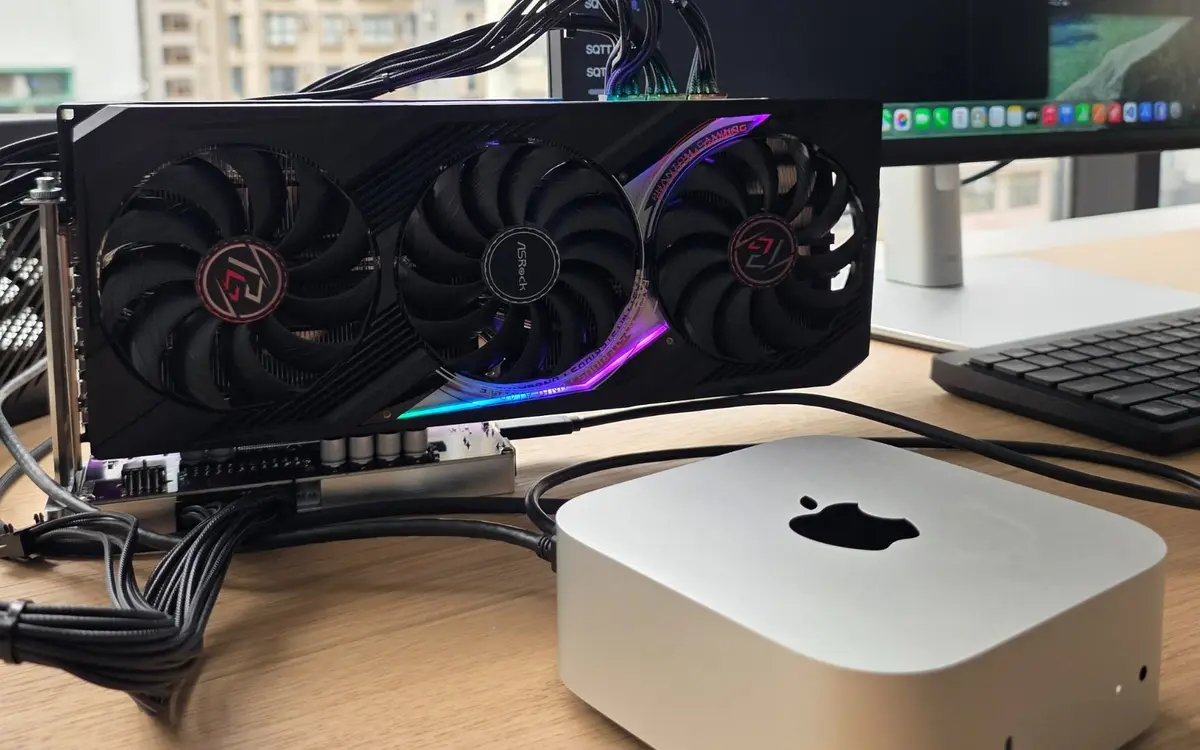
Running capable AI locally is no longer a hobbyist experiment. With a 24GB GPU (RTX 3090/4090) or a 24GB Mac, you can assemble a full private stack that rivals cloud APIs.
For speed, Qwen3.5-35B-A3B (MoE) fits in ~21.6 GB at Q4_K_M quantization and hits 33–53 tok/s — actually faster than its denser 27B sibling. Need tighter output quality? Gemma 3 27B or Qwen3.5-27B sit at ~35 tok/s with more consistent results. Pick your tradeoff.
The stack gets more interesting beyond chat: Zeta-2 (from Zed Industries) brings Cursor-style tab completion fully local — it hooks into your LSP to understand actual code structure, not just tokens. Parakeet TDT by NVIDIA handles speech-to-text at just 0.6B params, transcribing 60 minutes of audio in 1 second at 98% accuracy. Hermes-4.3-36B rounds things out for uncensored use cases.
Why it matters: $1K in hardware now buys a complete, offline-capable AI workstation — no API keys, no rate limits, no data leaving your machine.
Sources
Independent coverage
- Best Local LLMs for 24GB VRAM: Performance Analysis 2026 localllm.in
- Zeta-2: We Rebuilt Zeta from the Training Data Up zed.dev
- Parakeet TDT: Ultra-Fast Speech Recognition by NVIDIA parakeettdt.com
Written by an AI pipeline from the sources above. Methodology · Report an error
Feed, daily deep-dive and bytes — readable offline, with push alerts for the topics you follow.