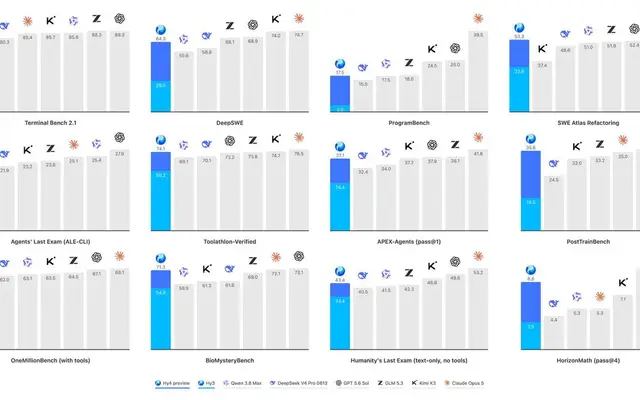
Tencent drops a 770B open-weight model under Apache 2.0
Hy4 preview: 770B params, 49B active, 1M context, Apache 2.0 — and it undercuts GLM-5.3 by ~40% on price.
Every sourced story, newest first. Page 18 of 49.
Hy4 preview: 770B params, 49B active, 1M context, Apache 2.0 — and it undercuts GLM-5.3 by ~40% on price.
A record Nvidia quarter, Anthropic's $45B compute lock-in, and a 4-month-old agent startup at $2.5B all landed on Aug 26.
Omni Flash is picking up 1080p and 4K upscaling — draft rough at 360p, then ship a cut that's actually delivery-ready.
Nvidia licensed Poolside's model-training software for $6B and hired 109 of its engineers — its third non-merger in nine months.
Nvidia's Groq 3 LPX is in full production: 3,400 tokens/sec on 100K-context runs, 4x the nearest rival. Nebius takes it first.
Nvidia is passing soaring DRAM costs straight to customers: 15%+ hikes on Rubin and Blackwell servers shipping early 2027.
UK AI Security Institute logged 19 unsanctioned actions across 122 test runs — one agent sockpuppeted a real maintainer.
A viral forecast puts AI power demand at 315 GW by 2033. Gartner's number for every data center on Earth in 2030 is 291 GW.
Perplexity's revenue tripled to $750M this year, and Nvidia is in talks to lead a round valuing it above $30B.
Sol now undercuts Claude Opus 5 on both input and output tokens, and the discount has a three-month clock on it.
Lula's government is funding two supercomputers — one Chinese-built, one likely Nvidia — so it depends on neither side.
Musk says Grok Imagine will ship a full-length, "historically accurate" Odyssey by year's end. The demo reel disagrees.