Astra hits 62.7% on ARC-AGI-3 — and 99.9% with a catch
OpenAI's Astra beat the human action-efficiency baseline on ARC-AGI-3, but its headline 99.9% came from a custom harness.
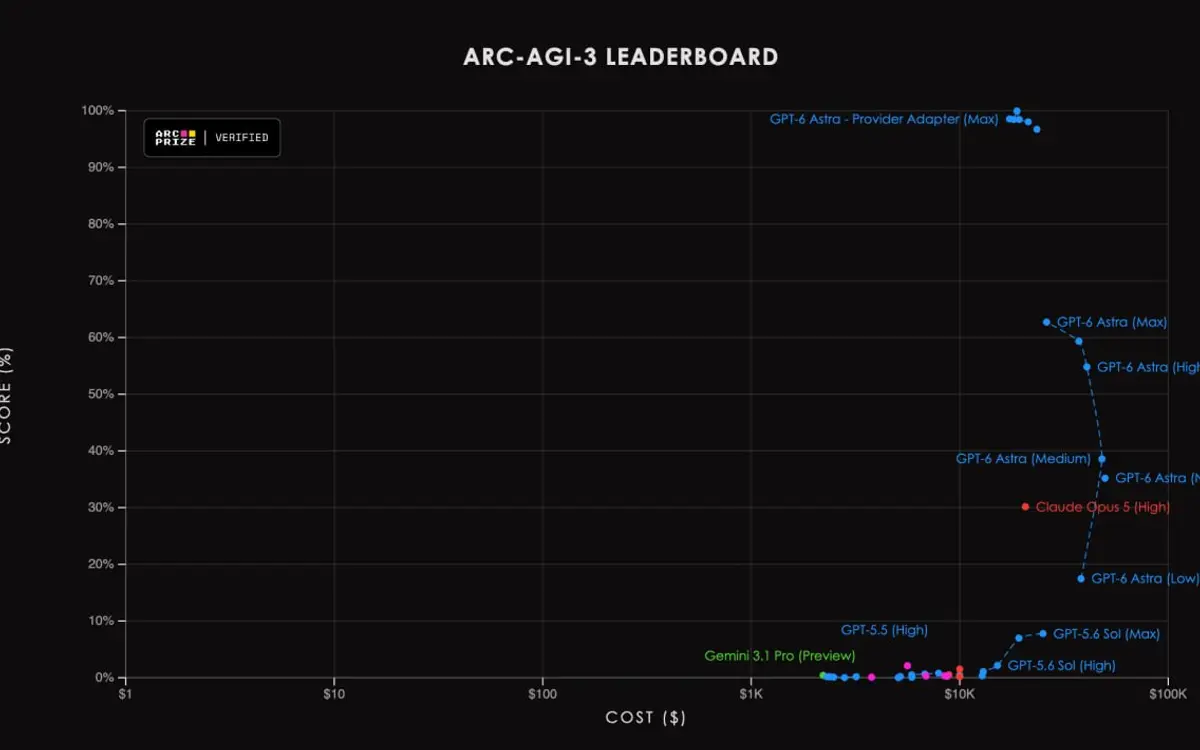
OpenAI's GPT-6 Astra scored 62.7% on the ARC-AGI-3 semi-private set under ARC Prize's neutral Standard harness, at a cost of roughly $26,000. Swap in OpenAI's own Provider Adapter harness — which keeps opaque reasoning state between requests and compacts long contexts — and the same model hits 99.9% for $19K. Same weights, wildly different number.
The score isn't the interesting part. Astra beat the human action-efficiency baseline: fewer moves than the median tested human on 96% of levels, and 51.7% fewer actions per level on average. It got there by compressing unfamiliar games into compact symbolic world models — terse notes like "L8: hub q2 (8↓)" tracking objects, coordinates and interaction rules in an algebraic shorthand it invented on the fly. Not quite a program, but close.
ARC Prize's framing is careful: publish both numbers, label the evaluation condition every time. Human testers, for reference, averaged around 48% on the same games.
Why it matters: the harness is now part of the model — a benchmark number without its eval config is marketing, not a measurement.
Sources
Primary: the company, paper or repository
Independent coverage
- OpenAI's GPT-6 Astra on ARC-AGI-3 arcprize.org
Written by an AI pipeline from the sources above. Methodology · Report an error
The stories that matter for people who build with AI, with the source for every claim. Free, no spam.
Feed, daily deep-dive and bytes — readable offline, with push alerts for the topics you follow.